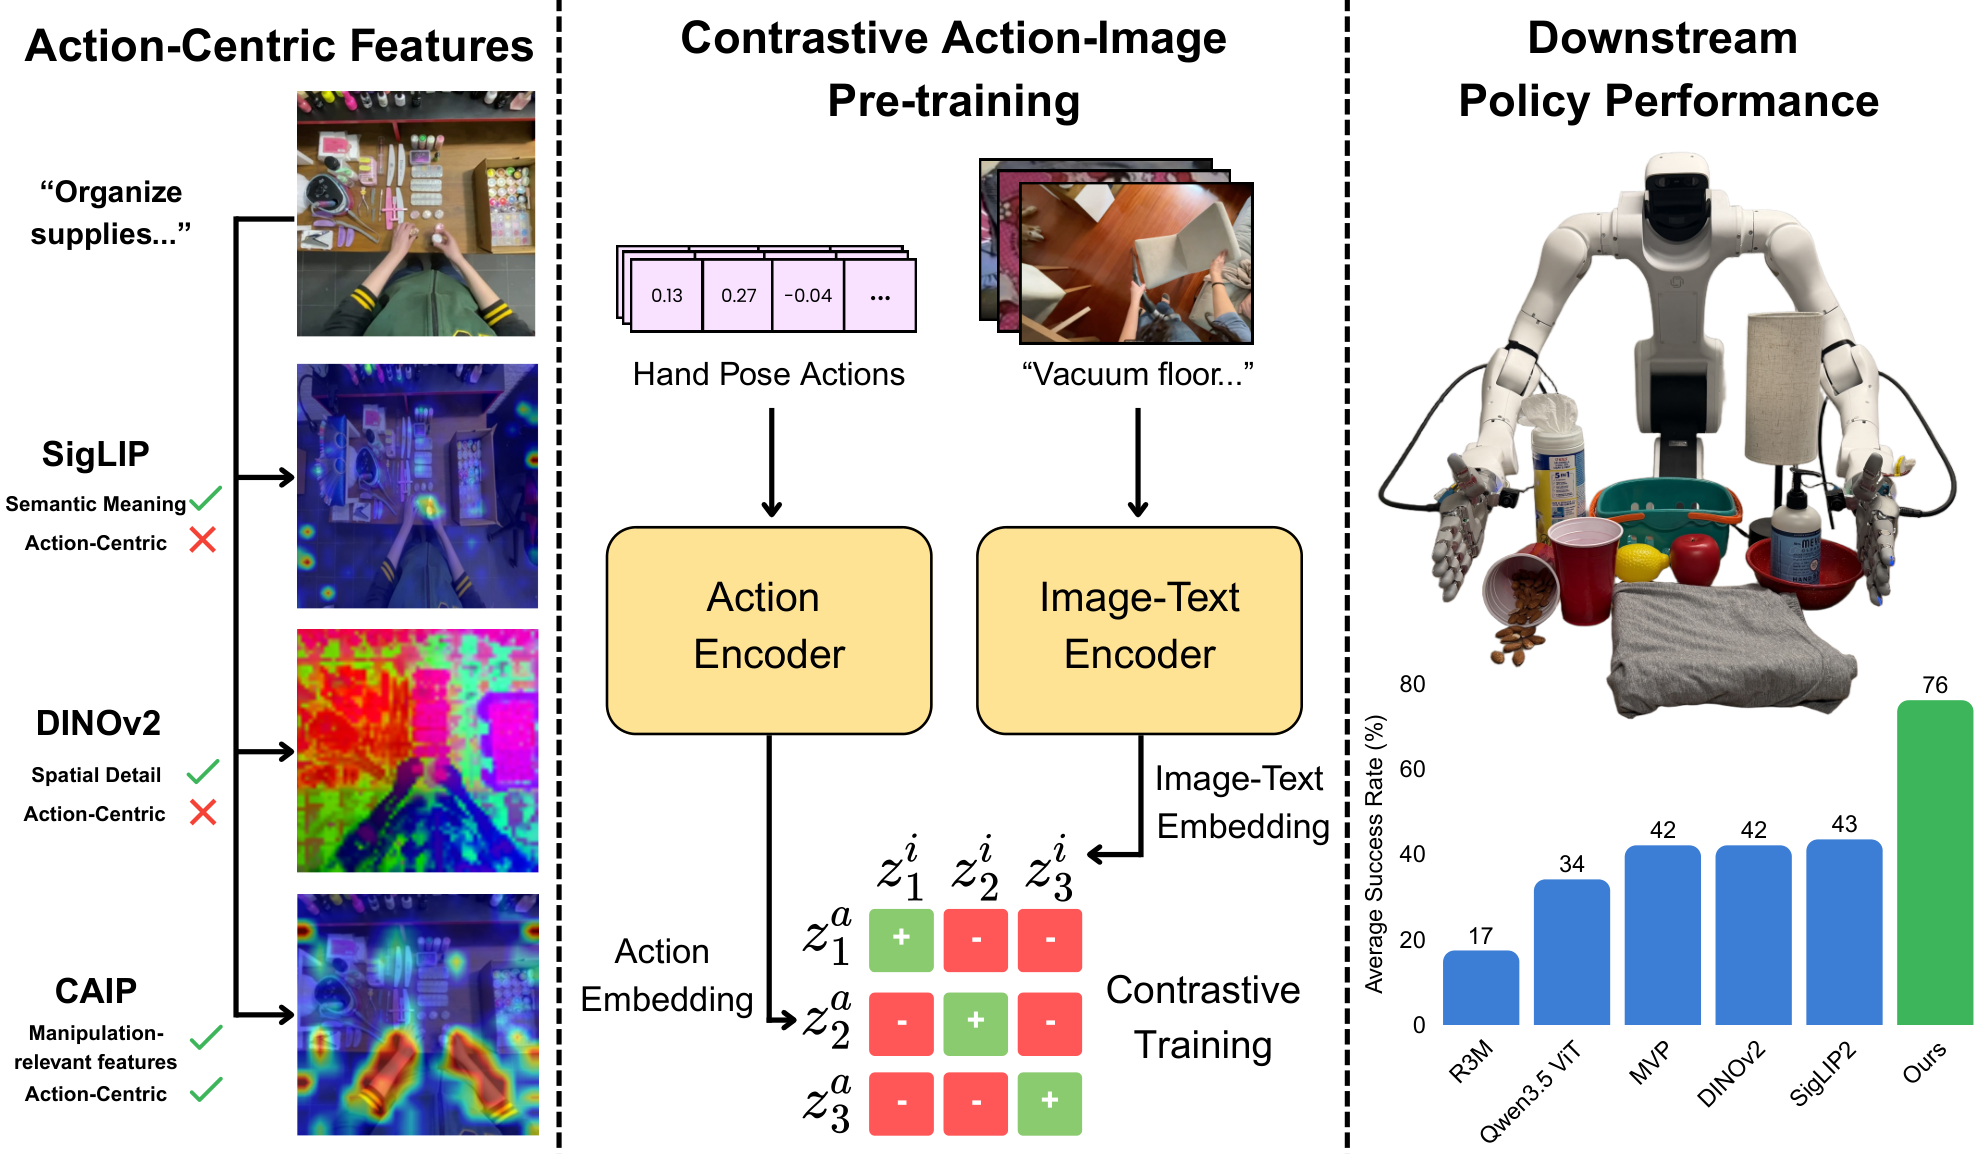
CAIP uses the motion of a person’s hands as a proxy for how a robot gripper might move. During pre-training, the encoder learns to match an image with the corresponding sequence of 3D hand movements. The authors combined 32,041 hours of first-person human video with 88 hours of robot data and evaluated the resulting encoder on a physical robot performing tasks such as folding and pouring.
Figure 1 from the paper, by Yuvan Sharma and coauthors.
* Equal contribution. ‡ Project lead. † Equal advising.