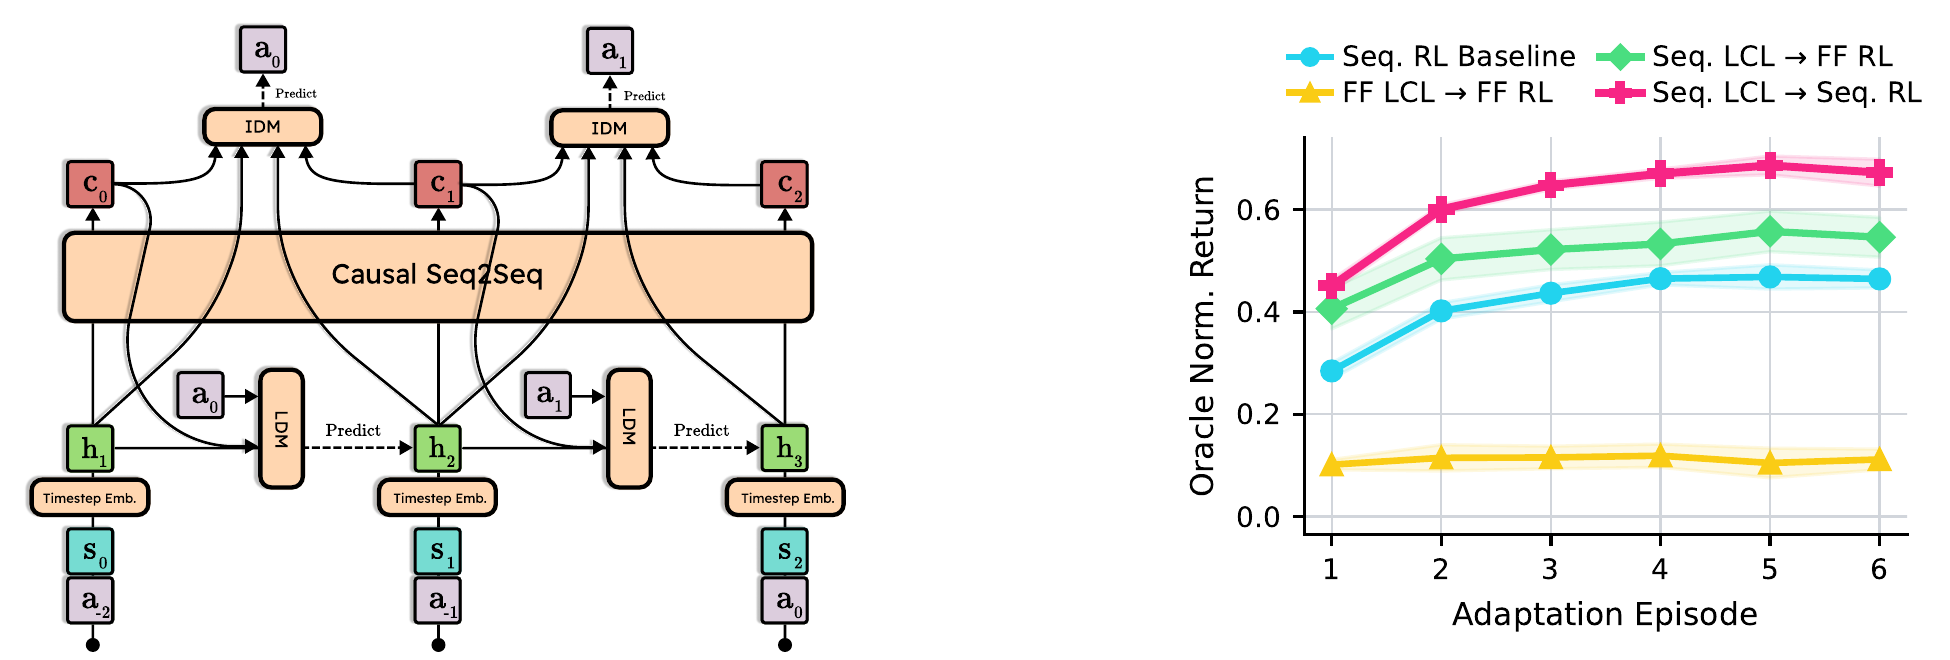
When an agent encounters a new task, it may need to learn both how a new environment works and which behavior earns a reward. MetaBFM trains on a mixture of experience with and without reward labels. At test time it can explore, use a strategy it has learned, or infer an objective from the rewards it observes. In experiments it matched supervised meta-reinforcement learning on familiar reward functions and adapted to objectives omitted from training.
† Equal contribution.