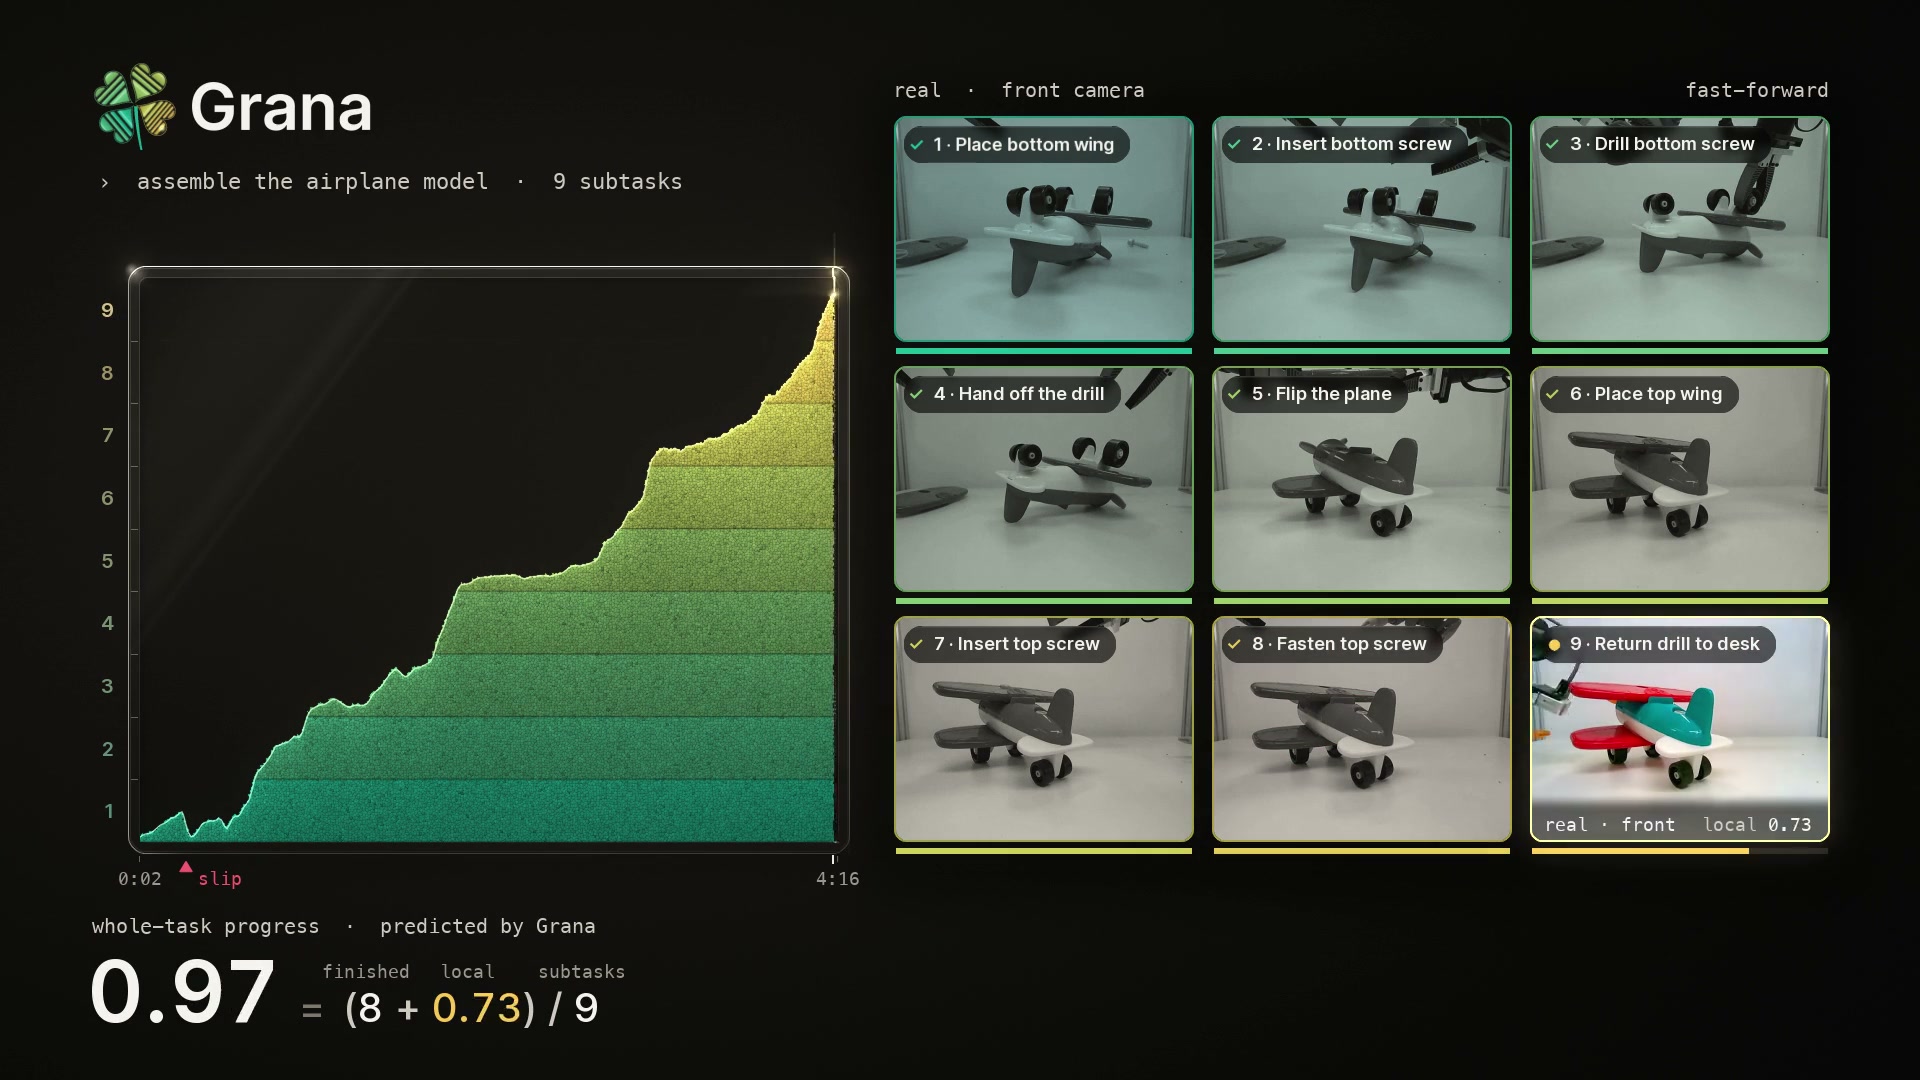
Grana is a vision-language reward model that measures progress on multi-step robot manipulation tasks. Given a sequence of subtask descriptions, it identifies the unfinished step, estimates progress within that step, and combines the estimate with credit for completed steps. If a robot loses its grip during an insertion, the estimated progress can fall while earlier assembly steps still count.
We convert sparse subtask boundaries and annotations of action quality into dense progress targets. Pretraining on 200 mostly short manipulation tasks supports reward prediction on unseen tasks and improves adaptation to five long-horizon tasks. On real robots, the same progress estimates guide policy training through reinforcement learning and action selection through model predictive control.
* Equal contribution. † Equal advising.